Would you oppose this being done with locally run LLMs whose models are open weight (preferably open source) driven by clean energy? (You don’t need a data center to do inference.) Because I don’t oppose “stealing” information when its proletarians doing the “stealing”. E.g., I’ve “stolen” literally thousands of textbooks and papers with LibGen and Anna’s Archive and SciHub, and I will never ever ever feel guilty about that.
Because if your opposition is to increased corporate control, then I get your frustration. I’m absolutely against the corpos controlling… literally fucking anything, but unfortunately they do control the compute these days, so in the short term these are the conditions we have to plan around. So this seems like using the capitalists’ tools against them. It’s obviously not as good as taking the capitalists’ tools away from them, but it’s something.
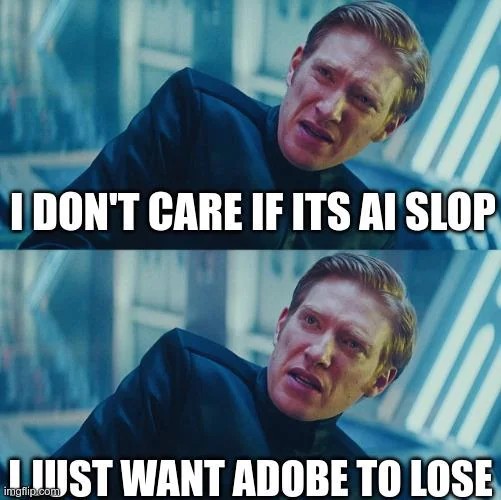
If you want to use this AI generated alternative of adobe because adobe is horrible, then I understand you…
Actually I don’t plan on using this particular tool. I typically just use GIMP or Krita since I’m not a professional, and I still want to see those ecosystems succeed. If anything, I hope it will convince GIMP to give users choices for GIMP to work like Adobe. I’m speaking up because in some circumstances, I absolutely do not oppose using or creating vibe-coded software from a technical perspective.
I guess I was assuming how this project was made, as some people have pointed out about its “clean-room” method, but checking the GitHub, the main contributor is Claude’s llm, which grabs everything and anything.
I should probably think about how I feel about locally run llms, because its not massive polluting and disturbing data centers, but again, the models themselves are trained on something, and even though you can’t get “good” models without a lot of training data, it would still be unethical, atleast in these cases. Slightly off topic at the end but I guess that’s just my main concern here.
I can also understand the view point of llms being “using the capitalist’s tools against them”, and in some ways you’re right, but I still think we should be aware of what were using and what were doing instead of just praising it in the name of fighting back.
I myself will still not like generative AI, simply because of all the shit and more, but also how damaging it has been for the creative space
Yeah I’m not claiming that the models were trained ethically. Like they basically scraped the entire Internet, definitely including some data it’s unethical to include. Thus, “stealing” isn’t really the right framework. It’s violations of privacy or other rights.
What you get when you download an “AI” (really a LLM, since these things are not intelligent like humans, and we wouldn’t want them to be because otherwise they would have rights) model is basically a big set of numbers. IMO the question is: what are the consequences of using these numbers?
In my view, the best, but ultimately unconvincing argument against using these numbers is that they were generated by an unethical process, so using these specific numbers constitutes an endorsement of the process that created them. As an anti-capitalist, I fundamentally oppose almost every process that created almost every product I have ever used, simply by virtue of the fact that everything I have ever owned has been produced by private firms stealing proletarian labor. If I applied this principle consistently, I would simply starve to death and be completely marginalized and forgotten by capitalist society. Thus, I am willing, to some extent, to live in contradiction of the heuristic that we shouldn’t use products derived from unethical processes. In particular, I believe that local LLMs, despite their ethically sketchy training, have sufficient technical utility for users to offset the harm already incurred. So I think there is absolutely an argument to slow down training of LLM models, especially since I suspect that the system you build a model into is just as important as the LLM “black box” itself (e.g. Claude uses a Linux container and SymPy in the background)…but for users, I don’t believe the argument to stop inference, i.e. using the numbers, is as strong.
I myself will still not like generative AI, simply because of all the shit and more, but also how damaging it has been for the creative space
Honestly, yeah I really am not interested in using LLMs for creative purposes. I only ever use LLMs for technical work, and I really only want to listen to music and consume art arranged by sentient beings.
I would also like to add that “AI” capitalists, like all capitalists, have issues with consent. Their loud insistence that “AI” is inevitable is a propaganda campaign to manufacture your consent for the vile things they want to do to you. Consequently, as someone who uses LLMs in my work, I emphatically reject the inevitability of LLMs, and if someone says they don’t want to use LLMs, I completely respect that choice and won’t bother them about it ever again. My view is that for some people in technical professions, in particular high-information fields, LLMs are and will be incredibly helpful tools…but a lot of people are simply never going to use LLMs and should not be pressured to do so. And as a corollary, we shouldn’t structure our entire goddamn society around these tools.

Would you oppose this being done with locally run LLMs whose models are open weight (preferably open source) driven by clean energy? (You don’t need a data center to do inference.) Because I don’t oppose “stealing” information when its proletarians doing the “stealing”. E.g., I’ve “stolen” literally thousands of textbooks and papers with LibGen and Anna’s Archive and SciHub, and I will never ever ever feel guilty about that.
Because if your opposition is to increased corporate control, then I get your frustration. I’m absolutely against the corpos controlling… literally fucking anything, but unfortunately they do control the compute these days, so in the short term these are the conditions we have to plan around. So this seems like using the capitalists’ tools against them. It’s obviously not as good as taking the capitalists’ tools away from them, but it’s something.
Actually I don’t plan on using this particular tool. I typically just use GIMP or Krita since I’m not a professional, and I still want to see those ecosystems succeed. If anything, I hope it will convince GIMP to give users choices for GIMP to work like Adobe. I’m speaking up because in some circumstances, I absolutely do not oppose using or creating vibe-coded software from a technical perspective.
I guess I was assuming how this project was made, as some people have pointed out about its “clean-room” method, but checking the GitHub, the main contributor is Claude’s llm, which grabs everything and anything.
I should probably think about how I feel about locally run llms, because its not massive polluting and disturbing data centers, but again, the models themselves are trained on something, and even though you can’t get “good” models without a lot of training data, it would still be unethical, atleast in these cases. Slightly off topic at the end but I guess that’s just my main concern here.
I can also understand the view point of llms being “using the capitalist’s tools against them”, and in some ways you’re right, but I still think we should be aware of what were using and what were doing instead of just praising it in the name of fighting back.
I myself will still not like generative AI, simply because of all the shit and more, but also how damaging it has been for the creative space
Yeah I’m not claiming that the models were trained ethically. Like they basically scraped the entire Internet, definitely including some data it’s unethical to include. Thus, “stealing” isn’t really the right framework. It’s violations of privacy or other rights.
What you get when you download an “AI” (really a LLM, since these things are not intelligent like humans, and we wouldn’t want them to be because otherwise they would have rights) model is basically a big set of numbers. IMO the question is: what are the consequences of using these numbers?
In my view, the best, but ultimately unconvincing argument against using these numbers is that they were generated by an unethical process, so using these specific numbers constitutes an endorsement of the process that created them. As an anti-capitalist, I fundamentally oppose almost every process that created almost every product I have ever used, simply by virtue of the fact that everything I have ever owned has been produced by private firms stealing proletarian labor. If I applied this principle consistently, I would simply starve to death and be completely marginalized and forgotten by capitalist society. Thus, I am willing, to some extent, to live in contradiction of the heuristic that we shouldn’t use products derived from unethical processes. In particular, I believe that local LLMs, despite their ethically sketchy training, have sufficient technical utility for users to offset the harm already incurred. So I think there is absolutely an argument to slow down training of LLM models, especially since I suspect that the system you build a model into is just as important as the LLM “black box” itself (e.g. Claude uses a Linux container and SymPy in the background)…but for users, I don’t believe the argument to stop inference, i.e. using the numbers, is as strong.
Honestly, yeah I really am not interested in using LLMs for creative purposes. I only ever use LLMs for technical work, and I really only want to listen to music and consume art arranged by sentient beings.
I would also like to add that “AI” capitalists, like all capitalists, have issues with consent. Their loud insistence that “AI” is inevitable is a propaganda campaign to manufacture your consent for the vile things they want to do to you. Consequently, as someone who uses LLMs in my work, I emphatically reject the inevitability of LLMs, and if someone says they don’t want to use LLMs, I completely respect that choice and won’t bother them about it ever again. My view is that for some people in technical professions, in particular high-information fields, LLMs are and will be incredibly helpful tools…but a lot of people are simply never going to use LLMs and should not be pressured to do so. And as a corollary, we shouldn’t structure our entire goddamn society around these tools.